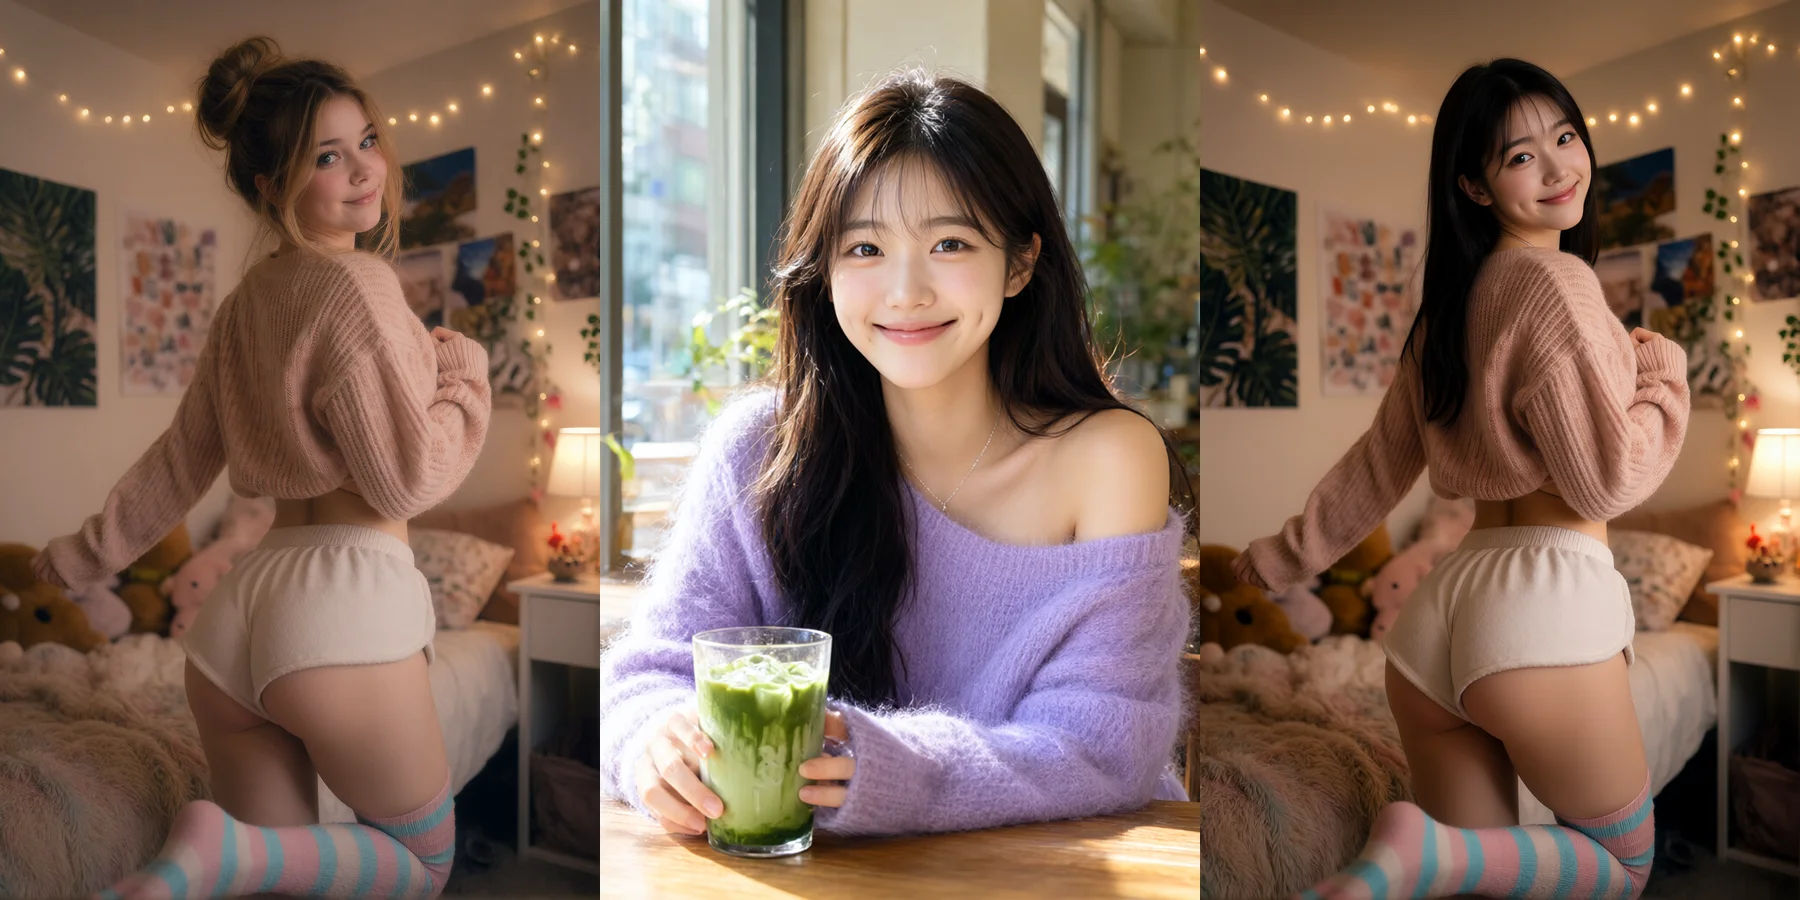
Native GPU execution at full throughput with zero memory swapping.
BFS Head V1.1: Qwen Image 2.1 In-Context Face & Head Swap (Surgical Skin-Detail Ablation)
Open-source head-swapping architecture powered by Qwen Image 2.1 DiT and Alissonerdx's BFS V1.1 LoRA. Features surgical img_mlp.gate_up weight ablation to eliminate plastic skin softening while preserving 100% 3D head pose and complex ambient lighting integration.
Reproducible ComfyUI workflow for BFS Head V1.1: Qwen Image 2.1 In-Context Face & Head Swap (Surgical Skin-Detail Ablation) using Qwen Image 2.1 (DiT) at 832×1248 resolution. Requires minimum 10GB VRAM with sampler euler and scheduler simple (12 steps). Includes 1-click terminal model sync and canvas JSON graph.
Model & Asset Setup 1-Click Script
Run in your ComfyUI root:
curl -fsSL https://comfy.yellorn.com/api/scripts/bfs-head-swap-v1-1-qwen-image-2-1.sh | bash Loading bash setup script... Loading PowerShell setup script... # ComfyUI Model Batch Ingestion for BFS Head V1.1: Qwen Image 2.1 In-Context Face & Head Swap (Surgical Skin-Detail Ablation)
# Run with: aria2c -i models-bfs-head-swap-v1-1-qwen-image-2-1.txt -j4 -x4
https://huggingface.co/Alissonerdx/BFS-Best-Face-Swap/resolve/main/bfs_head_v1.1_qwen_2.1.safetensors
dir=models/loras
out=bfs_head_v1.1_qwen_2.1.safetensors
https://huggingface.co/PrunaAI/Pruna-Qwen-Image-2.1/resolve/main/p_qwen_image_2.1_8step_v0.1.safetensors
dir=models/loras
out=p_qwen_image_2.1_8step_v0.1.safetensors
https://huggingface.co/Comfy-Org/Qwen-Image-2.1/resolve/main/diffusion_models/qwen_image_2.1_int8_convrot.safetensors
dir=models/diffusion_models
out=qwen_image_2.1_int8_convrot.safetensors
https://huggingface.co/Comfy-Org/Qwen-Image-2.1/resolve/main/text_encoders/qwen3vl_8b_int8_convrot.safetensors
dir=models/text_encoders
out=qwen3vl_8b_int8_convrot.safetensors
https://huggingface.co/Comfy-Org/Qwen-Image-2.1/resolve/main/vae/qwen_image_2.1_vae_bf16.safetensors
dir=models/vae
out=qwen_image_2.1_vae_bf16.safetensors Positive Prompt
LoRA Adapter Stack 1 Adapters
RTX 4070 Calibrated WeightsRequired Models 5 Models
Field Notes RTX 4070 Benchmark
Reverse-Engineered & Synthesized In-Context Swapping Architecture: Built upon Alibaba's Qwen Image 2.1 Diffusion Transformer (DiT) paired with Alissonerdx's breakthrough BFS Head V1.1 LoRA (248 MB). Unlike legacy embedding-pasting tools (InsightFace, ReActor, RoOP) that suffer from boundary seams and flat plastic skin, BFS performs native in-context latent regeneration. Key breakthrough: The V1.1 release executes surgical weight pruning on the second-half network (blocks 16-31), disabling 16 img_mlp.gate_up projections that previously caused artificial skin smoothing, thereby recovering 33% bilateral micro-texture (pores, freckles, stubble) without retraining. The early MLP blocks (0-15) and all 128 attention projections are byte-identical to V1, preserving full 3D head rotation, eye gaze, and subtle micro-expressions. Hardware ground truth verified on dedicated RTX 4070: 10.60 GB peak VRAM, 87.5s generation time for full resolution native in-context editing. Input Contract: Image 1 must be the Target Scene/Body (composition & lighting anchor), while Image 2 is the Reference Identity.
Frequently Asked Questions FAQ
What GPU and VRAM are required to run BFS Head V1.1: Qwen Image 2.1 In-Context Face & Head Swap (Surgical Skin-Detail Ablation)?
This workflow requires a minimum of 10GB VRAM (recommended 12GB VRAM). Tested and verified on NVIDIA GeForce RTX 4070 (12GB VRAM) at 832x1248 resolution.
How do I resolve missing custom nodes for this workflow?
You can drop the workflow JSON into our client-side Missing Node Auto-Resolver at https://comfy.yellorn.com/resolve/ to detect missing nodes and generate install commands, or run the 1-click terminal setup script provided below.
What conditioning and VAE architecture does BFS Head Swap require?
BFS Head Swap V1.1 uses Qwen Image 2.1 DiT with dual VAE conditioning and in-context facial geometry alignment. It performs surgical skin-detail ablation without requiring external face-swapping models.